
New open-source LLM? We test it for your use case.
Your model monitoring for open-source LLMs
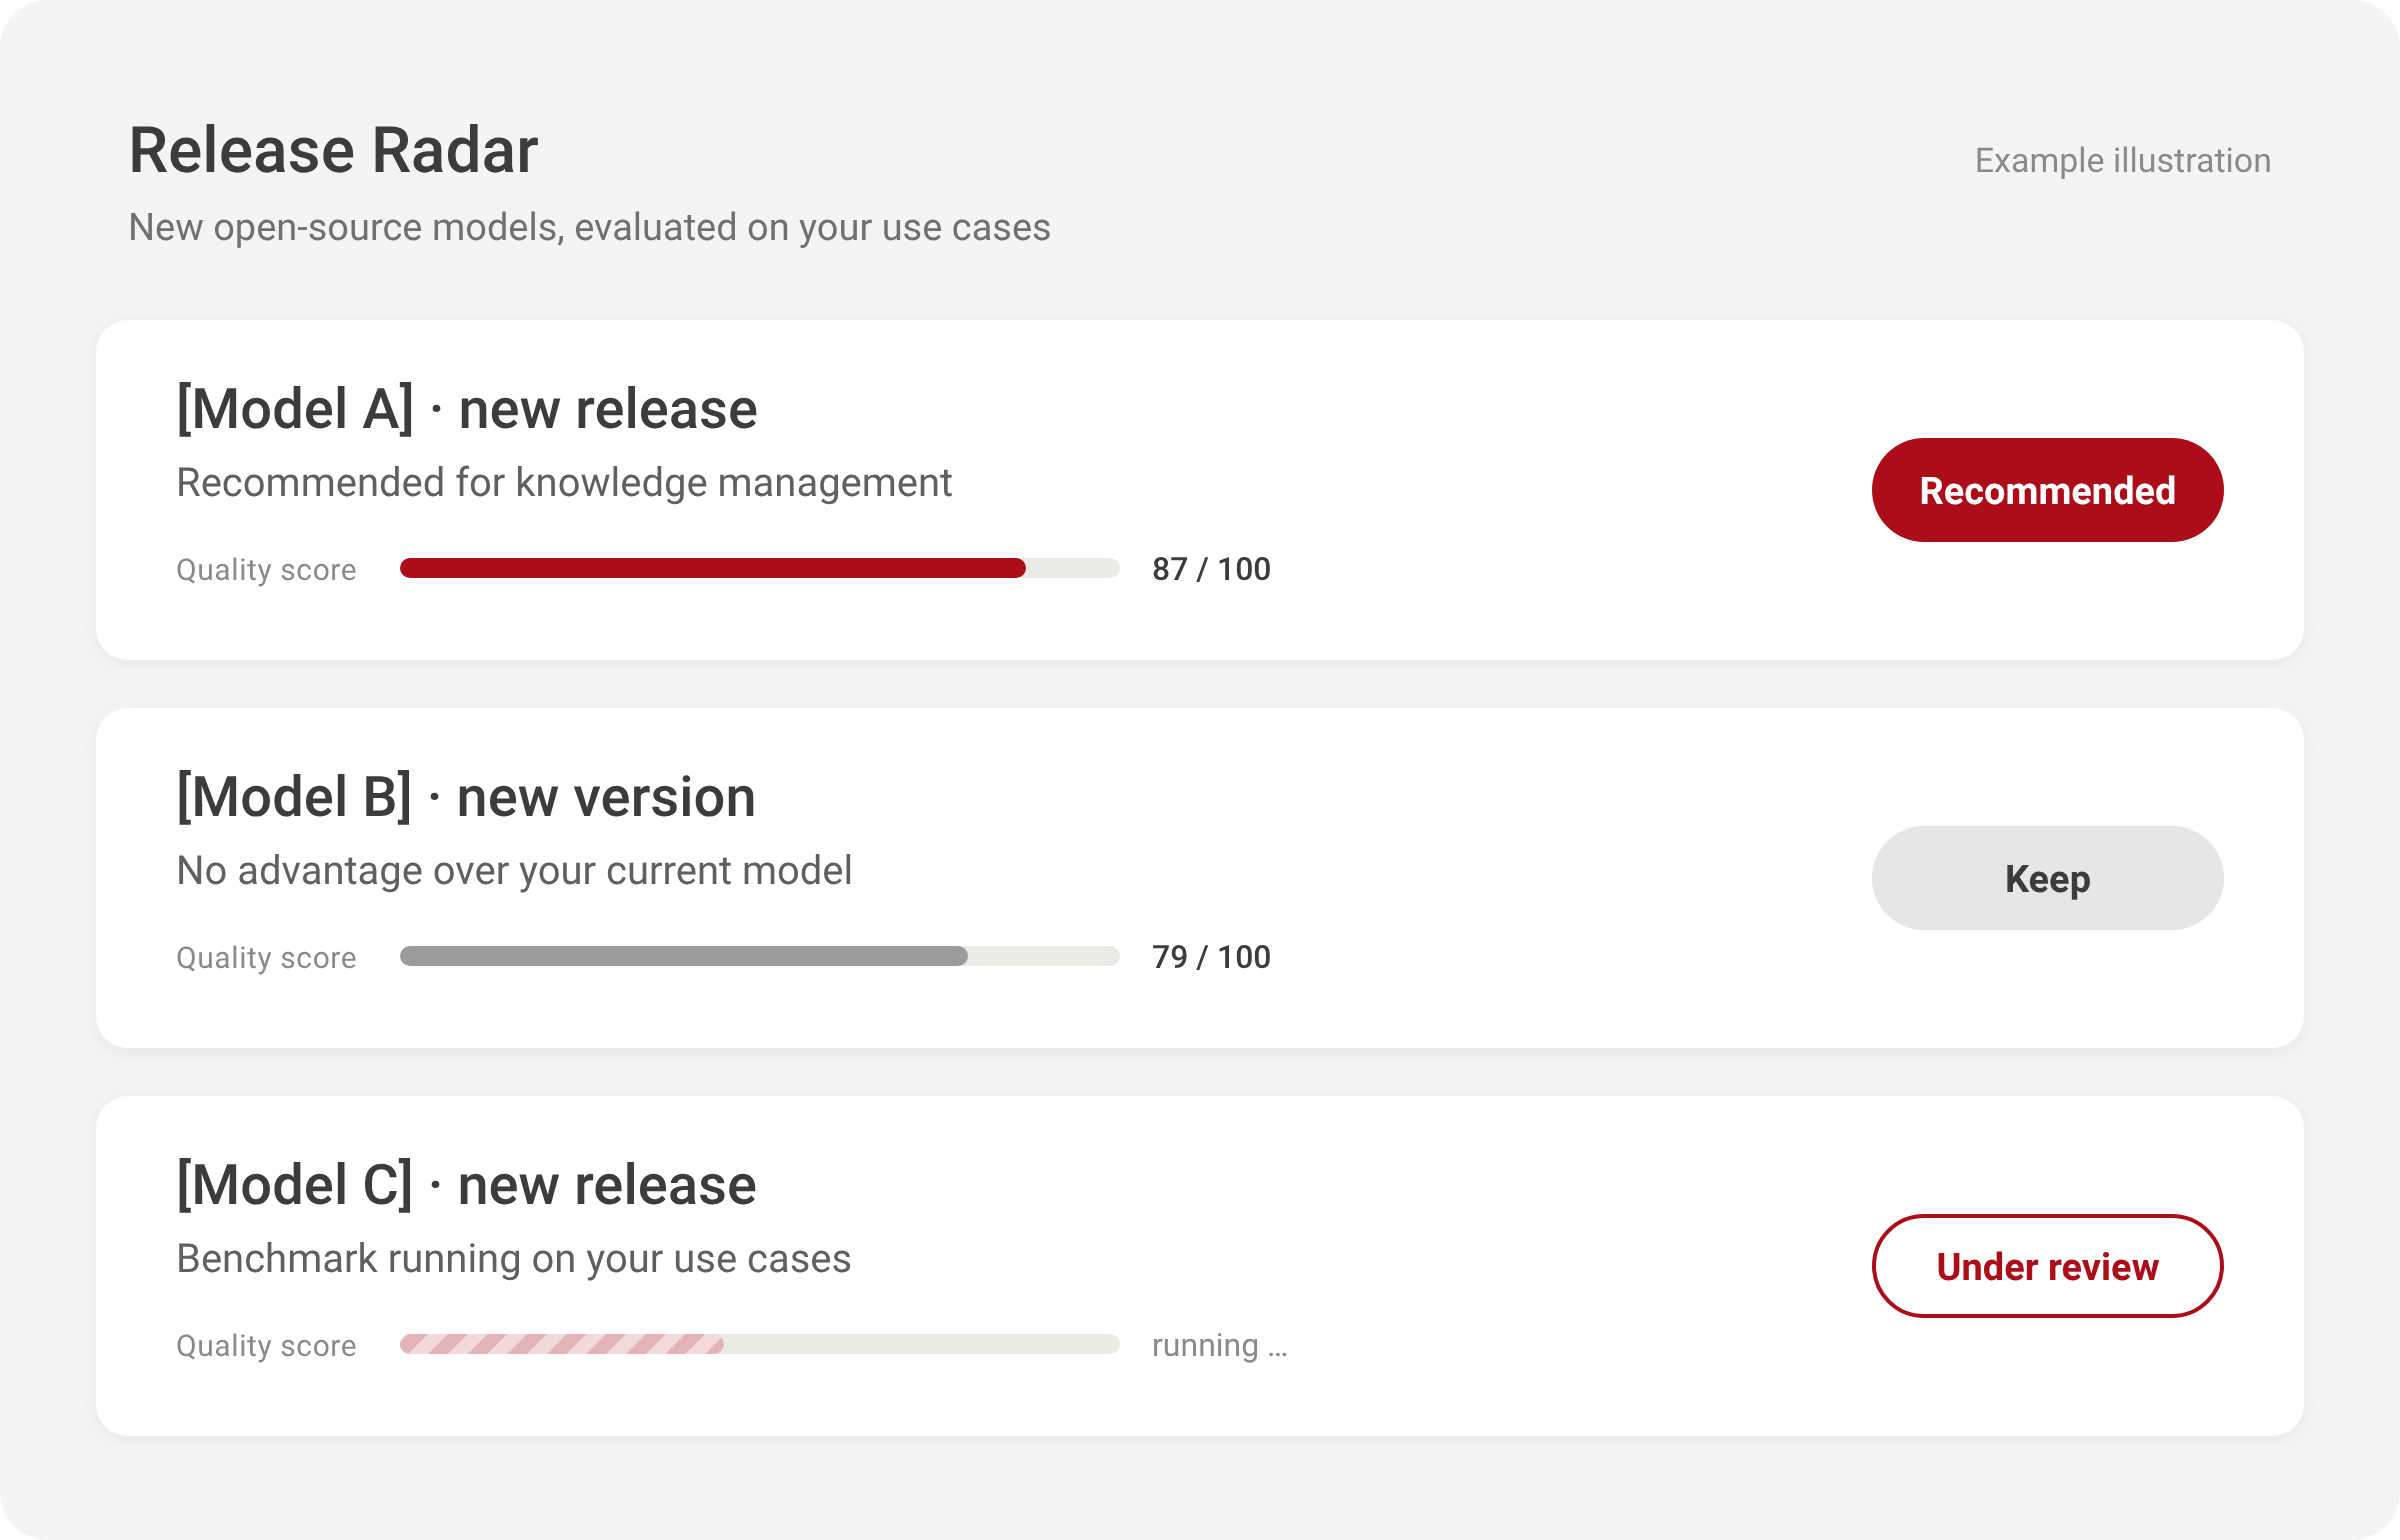
- Every relevant release on our radar: We continuously track the open-source market and evaluate new models and model versions as soon as they are released – using a fixed, transparent methodology.
- Recommendations for your use case: We know our customers' use cases. That's why we tell you specifically whether switching is worthwhile – knowledge management may call for a different model than specialist research.
- You set the framework: Local open-source model, cloud model or both: we advise proactively but fully follow your requirements – including models of your choice.
Five steps from new release to well-founded recommendation
How our benchmark works:
- Define the test basis: 500 to 2,000 pseudonymized documents, plus typical domain questions with known, correct answers.
- Test models automatically: The questions are sent automatically to an AI assistant with access to the documents – every model under the same conditions.
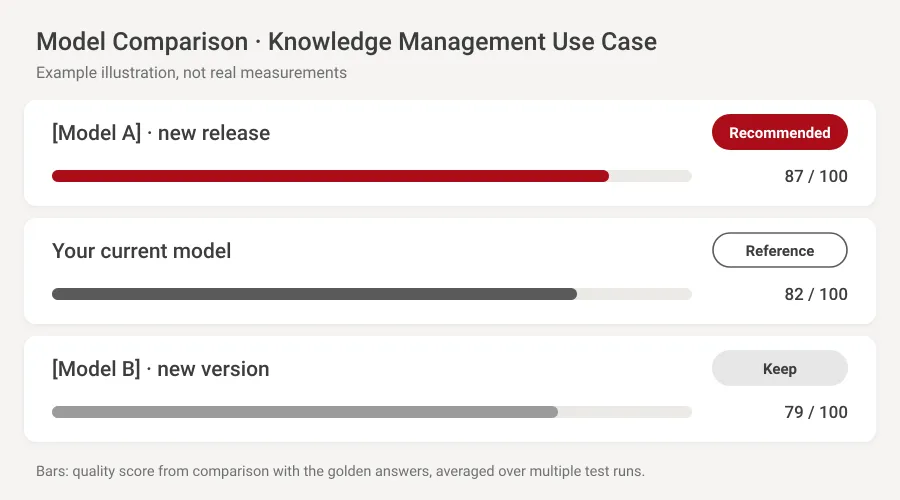
- Evaluate answers: Comparing them with the reference answers (golden answers) produces a quality score per model.
- Compare results: Multiple test runs smooth out fluctuations and show how reliably a model really answers.
- Analyze weaknesses: Conspicuous answers are examined with AI support. This lets us identify error patterns and derive improvements.
Measured, not estimated: Why public LLM rankings are not enough
Vendor claims and public leaderboards say little about how well a model handles your documents and your questions. Our benchmark does.
For each model, you receive a quality score, a statement on reliability across multiple runs and a clear recommendation – transparently documented and repeatable at any time.
What LLM benchmarking from IntraFind does for you
 Objective model comparison: Evaluate different LLMs on identical tasks.
 Practical evaluation: Realistic, business-relevant questions instead of abstract benchmarks.
 Transparent quality: Measurable scores make performance and reliability transparent.
 Faster model selection: Systematically check new models and versions for suitability – without any testing effort on your part.
 Targeted optimization: Weaknesses become visible and can be specifically investigated and fixed.
We recommend proactively. The decision remains yours.
Advice, not prescriptions
Our platform is model-agnostic. Whether you follow our recommendation, stay with your proven model or have a model of your choice tested: we implement what fits your requirements, your operating model and your compliance rules.
- Local open-source models, commercial cloud models or a combination
- Benchmarks on your own questions and documents
- Model changes reversible at any time – no LLM vendor lock-in
- Personal consulting from experts who know your use cases
When LLM benchmarking pays off for your company


Secure, sovereign, compliant
✔️EU AI Act - The Enterprise AI Platform complies with the AI Act (EU) 2024/1689
✔️GDPR-compliant - Privacy-compliant operation in accordance with the GDPR
✔️No model training with customer data - Your data is not used to train AI models
✔️Data residency - You decide where your data is processed and stored
✔️Software Made in Germany


